Health Data: Analysis of the UK Biobank Model
Rédigé par Sohane Aissa
-
25 September 2026On April 14, 2026, the Financial Times and The Guardian revealed that the genetic data of more than 500,000 British citizens had been put up for sale on the Chinese platform Alibaba. A look back at this incident which highlights the importance of proper security of data sharing systems for health research.
The UK Biobank: an open scientific resource
The initial ambition and the constitution of the database
Launched in 2003 and opened to researchers in 2012, the UK Biobank (UKB) is a health database specifically constituted for scientific research. It is managed by a non-profit organization, steered by an independent scientific board of directors and hosted on the servers of the University of Manchester. For its funding, the structure relies on both public funds, through the Medical Research Council, and private funds through the Wellcome Trust, a charitable foundation.
This cohort has become one of the largest in the world: it brings together the data of more than 500,000 British volunteers aged 40 to 69 at the time of their inclusion in the study, and its resources have already enabled more than 18,000 scientific publications. It allows scientists to track the evolution of their health status over several decades in order to study the risk factors of complex chronic diseases (cancers, diabetes, cardiovascular diseases, etc.).
The following protocol was put in place in order to feed this database:
- The people were first identified from their health records, thanks to the official registers provided by the NHS (National Health Service, the British public health service) before receiving an information letter proposing to them to participate in the study and to collect their consent to the use of their data in the context of research.
- They then filled in detailed medical questionnaires (lifestyle habits, diet, family history) followed by a series of physical measurements (height, weight, etc.). The teams also collected biological samples (blood, saliva, urine) for biochemical analyses and the sequencing of their DNA.
- For at least 60,000 of them, this process was enriched at regular intervals by in-depth imaging examinations (notably MRI of the brain and heart), in order to observe in detail the structure and evolution of their organs.
- At their inclusion, the participants accepted not only this initial collection, but also the continuous and permanent enrichment of the database through the updating of their medical information entered directly by the NHS from their computerized medical record.
The pseudonymization mechanism: protecting the volunteers against the risk of re-identification?
To protect the volunteers who agreed to share this large amount of sensitive information, the UK Biobank applies a "de-identification" protocol:
- The creation of the internal identifier (or PID): the data are pseudonymized in a summary manner from their collection, that is to say that the names and first names of the person participating in the research are removed from the working files and replaced by a permanent internal identifier, called PID (Participant Identifier). This code, accessible to a restricted number of UKB staff members, is used solely to link the new NHS medical records to the correct samples over the years. It is an internal identifier, which is subject to particular security measures and is never provided to researchers.
- The substitution by a project code (or EID): when the data are made available to a researcher, the internal identifier (PID) is replaced by another identifier, specific to the research project, called EID (External Identifier).
- Thus, the same participant is designated by a different EID identifier according to the research projects, in order to limit the possibilities of cross-referencing between databases. If the same research team conducts two distinct studies on the database, it will have to make two independent requests and if the same person is present in both datasets, they will be identified by two different EID codes.
Access to the data and the sharing protocol with research teams
The policy of making the UK Biobank data available is characterized by a will for international openness. Thus, any researcher can request access to the cohort data, whether they belong to the academic, hospital or private commercial sector (such as biotechnology companies or pharmaceutical laboratories), and regardless of the nationality of their structure.
To obtain these files, the researchers' process is organized in three steps:
They register their affiliated institution and submit a form detailing their scientific project. The institution provides an administrative description of its structure, while the researchers commit to respecting the rules, particularly in terms of data protection, on a declaratory basis (there is for example no prior audit of the computer security of their servers by the biobank).
The request is then examined by an independent scientific committee (Access Committee), composed of scientists, doctors, lawyers, compliance specialists and ethics experts. This committee evaluates the scientific quality of the project and its compliance with ethical requirements.
Once the request is approved, the researcher signs a Material Transfer Agreement (MTA). Through this contract, the requesting organization commits to processing the data in accordance with the UK GDPR. The institution and its researchers are required to respect the purposes of the project, to implement appropriate security measures, not to share the data with third parties and to refrain from any attempt at re-identification or contact with the volunteers. The researchers can then receive several terabytes of data directly on their infrastructure to begin their analyses.
A database that is also a strategic asset and the associated risks
The UK Biobank also constitutes a strategic financial asset. By signing the consent form, the participants who agree that their data are used expressly declare "relinquish all rights to these samples which I am donating to UK Biobank". The text also specifies that the volunteers will not be able to derive any financial benefit from any commercial developments or treatments resulting from the research conducted on the database. This relinquishment applies exclusively to the material property of the biological samples and to the intellectual property rights that could result from them, without impacting their rights over their personal data guaranteed by the GDPR (notably the right of withdrawal).
Although the structure defines itself as the "steward" of this resource for the public good, its governance conditions and its legal statutes have explicitly anticipated the scenario of the bankruptcy or liquidation of the organization, by providing for the possibility of a transfer or total resale of the database to a third party. There are precedents – relatively recent – of sale or bankruptcy, concerning actors managing genetic databases, which is not without raising issues for people and their rights:
- The case of the genealogical database GEDmatch illustrates the risk related to the buyout of infrastructure. This site, originally designed to find relatives, was entirely resold to the company Verogen, which opened access to the database to the FBI to conduct police investigations and solve cold cases (old criminal cases that remained unsolved). After this buyout, in July 2020, the platform suffered two successive cyberattacks. As reported by the New York Times, a security flaw overwrote the site's privacy settings, then opening access for the FBI and law enforcement to the profiles of nearly one million users who had explicitly refused to participate.
- The crisis experienced by the company 23andMe also raises this question of the sustainability or durability of this type of databases. The American pioneer of consumer genetic testing relied on a model consisting of selling tests at low cost, before suffering a data breach in October 2023 affecting nearly 7 million customers. This crisis, combined with financial difficulties related to the lack of renewal of purchases, led to the collapse of its stock value and the mass resignation of its board of directors. The company filed for bankruptcy and was ultimately bought by the TTAM foundation for 305 million dollars, after a competing offer from the pharmaceutical group Regeneron. Approximately 15% of customers requested the deletion of their DNA profile following these uncertainties about the future of the database. This situation reminds us that when a company is bought out, uncertainties can arise about the future of the data it recovers.
The Alibaba affair: a diversion without hacking
A diversion of "legitimate use"
In April 2026, several British media revealed that data from the UK Biobank were offered for sale on the Chinese platform Alibaba. The files concern the entirety of the database, that is to say the genetic data of nearly 500,000 participants as well as the associated health information and sociodemographic data.
Contrary to what one might think, the UK Biobank infrastructure was not the victim of a cyberattack. The data had been legally obtained in the form of downloads by researchers whose projects had been approved by the scientific committee and who had authorized access under a data provision contract.
Once copied onto their own infrastructure, these data were the subject of three sale announcements on the Alibaba platform, in violation of the contractual commitments concluded with the UK Biobank. Detected on April 20, 2026, these three announcements were deleted within a few days by Alibaba which implemented automatic keyword filters to block any future resale and before any financial transaction could be made.
The multiplication of recipients: a structural risk
The multiplication of recipients of health data generates a major risk: the more the number of actors accessing the data increases, the more difficult it becomes to guarantee security and the more numerous the possibilities of diversion become. Security does not depend only on the technical infrastructure, but also on the behavior and security practices of each recipient. The level of security thus depends on the least vigilant actor.
The direct transfer of data to international research teams accentuates this risk, when the files circulate between countries with very different security rules and practices. Furthermore, the longer the chain of recipients becomes, the more the link between the producers of the data and their actual users becomes indirect, progressively diluting the sense of responsibility around the protection of this sensitive information.
This phenomenon of dilution and loss of control recalls the abuses observed in the economy of data brokers, where geolocation data collected by mobile applications (for example, mobile games or weather apps) are aggregated, resold and disseminated among a multitude of actors, making it impossible for the people concerned to know who holds their information or for what purpose it is used. The investigation by the newspaper Le Monde thus shows that data presented as pseudonymous can be re-identified in a few minutes thanks to their cross-referencing with other information (see also the Geo Trouve Tous project by LINC).
A very simple concealment mechanism and the limits of contractual control
To carry out this diversion without triggering the UK Biobank's alerts, the authors of the diversion prepared their files by applying the following concealment method:
- Fragmentation: the massive databases were cut into pieces.
- Renaming: the project codes (EID) and file names were modified.
- Cleaning: the metadata and all invisible digital fingerprints were erased.
This approach aimed to prevent tracing back to the authors. By deleting the immediate traceability of the files, the fraudsters attempted to mask the imputability of the diversion.
Thanks to an email sent anonymously by a researcher based in China, the UK Biobank was able to trace back to three projects conducted in Chinese institutions. The investigation report published by the UK Biobank revealed that the leak came from Xiangya Hospital, where a non-registered research student used a colleague's credentials to extract and put the data for sale on Alibaba, and from Tongji Hospital, where a temporary non-accredited employee accessed the database through the account of an official researcher.
The security model of the database shows here its limits: even if the original platform is well secured, control weakens considerably as soon as the data are exported to a third-party system. No technical mechanism prevents their duplication and transmission to third parties. For the original hosting platform, it is impossible to ensure with certainty that they remain only accessible to their legitimate recipient. Control relies solely on contractual commitments and on the trust given to the recipients. This incident therefore recalls the risks of misuse of personal data when they are primarily protected by contractual measures.
An older problem of negligence
The UK Biobank affair is part of a series of precedents related to the handling of data by researchers. As early as 2022, the organization noted that fragments of health data were appearing in open access on GitHub, the code hosting platform. In this case, it was not malicious researchers, but scientists who were sharing their code without realizing that they were leaving raw health data attached to the file.
A study conducted by the researcher Luc Rocher, from the University of Oxford, demonstrates the extent of this phenomenon. Between July 2025 and April 2026, the UK Biobank had to intervene 110 times to request the deletion of participants' data thus left in the clear on the web. The problems related to a download – sometimes exhaustive – of the data already existed before the Alibaba affair.
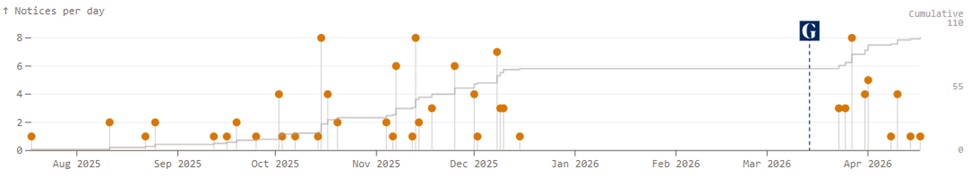
Figure 1: Timeline of takedown notifications (DMCA) issued by the UK Biobank to GitHub. Source: biobank.rocher.lc
The switch to cloud-only in 2024
To stop the leaks related to local downloads and secure the cohort, the UK Biobank imposed on July 25, 2024 the mandatory use of its cloud platform, UKB-RAP, through an investment of 16 million pounds sterling with Amazon Services (AWS). Developed with DNAnexus (an American company specializing in the secure analysis and management of genomic and biomedical data), this virtual space allows researchers to analyze genetic and medical data directly on the servers managed by the UK Biobank rather than retrieving the files on their own computer. The investigation report of June 1, 2026 however shows certain limits to this confinement: if the system blocked the extraction of source data, it left the possibility for researchers to automatically download the result of their analyses.
This mandatory centralization of analysis work on UKB servers provoked resistance among neuroscientists and medical imaging specialists. The analysis of heavy files (such as brain or heart MRI), previously free on their own computing tools, became financially heavy on the paid cloud. The UK Biobank thus had to maintain an administrative procedure of derogation authorizing off-cloud download (download exemptions). The Monitoring Committee indicates that approximately 200 international institutions thus retained the right to extract raw data off the cloud after 2024.
Another model is possible: the OpenSAFELY platform
This freedom of extraction highlights a fundamental difference with the OpenSAFELY platform, an alternative model developed by the University of Oxford in 2020 to respond to the urgency of COVID-19 without exporting or disclosing patients' records outside their secure storage environments. Their operations are opposed to that of UKB-RAP on two major points:
- Access to the data: on UKB-RAP, researchers perform their analyses by interacting directly with the individual data of the participants. In contrast, on OpenSAFELY, they never touch the real data. They work on synthetic data ("fake" data that have the same format as the original data). Once they have written the algorithms allowing them to perform their statistical analyses, this computer code is subject to a prior review to verify that it does not contain suspicious instructions. Only after validation is the code transmitted to a secure server to run automatically where the real NHS data are stored.
- Control of outputs: on the UK Biobank, the download of results was automatic. In contrast, OpenSAFELY imposes an output declaration procedure with a mandatory double human control: two people manually verify each graph or table to ensure that it does not allow indirect re-identification of individuals before authorizing its output.
On June 1, 2026, following the sale of the data on Alibaba, the government suspended access to UKB-RAP. Among the nine recommendations formulated on this occasion, the platform will remain closed until an output verification system (Output Checking System), initially manual, is deployed. Furthermore, access to health data from NHS medical records remains frozen and audits will force the permanent deletion of all histories still stored locally by laboratories around the world. The UK Biobank investigation report indicates that there were still 1,200 active projects initiated before 2024 with local data, to which is added the entire set of 200 institutions that benefited from post-2024 download exemptions.
Public reaction and real risks for citizens
The positions of the management and public authorities
The affair generated significant media coverage in the United Kingdom, notably in The Guardian and the Financial Times, before being picked up in France by the newspaper Le Monde. This scandal reignited debates on the sovereignty and protection of research data in health.
Faced with the criticism, the CEO of the UK Biobank, Rory Collins, in remarks reported by Le Monde, assured that it was "neither a leak, nor a cyberattack", but a "legitimate download by a legitimately accredited organization". According to him, imposing manual measures or overly restrictive controls would risk slowing down medical research and the discovery of treatments for cancer or Alzheimer's disease. In this same line of defense, the scientific director Naomi Allen insisted on the exclusive responsibility of "malicious researchers" rather than on the risks posed by their system.
In an official letter addressed to the participants on June 4, 2026, Bernard Taylor, chairman of the UK Biobank monitoring committee, presented his official apologies on behalf of the institution, publicly admitting that the structure "had not moved fast enough in monitoring the use of the data by researchers".
The political reaction of the British government was immediate, and of a rather different nature. Qualifying the security of data in the United Kingdom as a "priority for this government", the British Secretary of State for Technology, Ian Murray, intervened before Parliament to demand from the UK Biobank the immediate implementation of a new access control system.
DNA, a collective and unique data
This affair also fueled a deep concern within public opinion, leading to a loss of trust towards research infrastructure.
Participants in the cohort expressed a feeling of betrayal in the face of these failures. One of them, a septuagenarian re-identified during the investigation thanks to her month of birth alone and the date of a surgical intervention, questioned the respect of the commitments made: "I am more concerned about the respect of the agreement concluded with the participants. They had promised to guarantee the security of our data… I believe that this element must be taken into account."
The experts interviewed by The Guardian criticized the reaction of the UK Biobank management, which suggested that the risk came from the information shared by the participants themselves on the Internet. Professor Felix Ritchie (University of the West of England) was indignant at this position: "Do these people know that the Internet exists? It is totally unreasonable to think that they can be certain that their volunteers will never disseminate other information about them."
For his part, Professor Niels Peek (University of Cambridge) qualified the frequency of these leaks as "shocking", adding that: "The scale and persistence of these actions demonstrate the strong tensions between the ambition to conduct large-scale health research thanks to data and the legal and ethical imperative to protect the privacy of individuals."
As highlighted by Dr. Luc Rocher (Oxford Internet Institute), a simple cross-referencing of data can quickly reveal extremely intimate elements: "Once identified, this record could reveal sensitive information such as a psychiatric diagnosis, an HIV test result or a history of drug addiction."
This crisis highlights a fundamental scientific and ethical reality: DNA and health history are not classic personal data, but pluripersonal data. A genetic profile does not belong to only one person, it is largely shared with their biological family. Choosing to share one's genetic heritage therefore implies the medical confidentiality of their relatives: in case of a leak, it is also the children, parents and collateral relatives of the participants who find themselves exposed on the Internet, without ever having been consulted, or having given their consent.
The risk of re-identification by data cross-referencing in the era of AI
To reassure the public, the UK Biobank management advanced that the files sold on Alibaba "contained no personal identifying information" (such as names or addresses). It nevertheless had to acknowledge that these profiles included the sex, age, month and year of birth, socioeconomic status or even the lifestyle habits of the volunteers in addition to all the health information related to each individual.
An editorial published in April 2026 in the medical journal The BMJ recalls that de-identification does not guarantee anonymity: "in datasets containing common demographic and health attributes, individual records are often unique and vulnerable to re-identification, even when these datasets are incomplete."
From the point of view of data protection law, it is important not to confuse pseudonymization (also called de-identification) and anonymization, two concepts strictly regulated by the GDPR and clarified by the European Data Protection Board (EDPB):
- Pseudonymization consists of replacing direct identifiers (name, first name, social security number) with a code or pseudonym. It reduces the risks of direct re-identification, but does not eliminate the possibility if this code is crossed with other contextual information. The data therefore remains personal data subject to the GDPR.
- In France, the CNIL (through notably the reference methodology (MR) 004) applies it by imposing a unique pseudonym (or sequence number) specific and different per study for each patient. Only the controller of the initial database retains the correspondence key, which prevents researchers from cross-referencing data from multiple projects.
- Anonymization, in contrast, requires an irreversible process that makes any re-identification of the person impossible, even by cross-referencing or individualization. Only truly anonymized data fall outside the scope of the GDPR.
These databases do not amount to raw genetic code, they associate it with several other variables: age ranges, precise dates of care, hospital diagnoses or geographical data. With the development of open-access genealogical databases, the power of AI algorithms and access to public files (electoral rolls, social networks or civil data breaches), these sociodemographic attributes become all the easier to cross-reference.
Sometimes these ancillary data are sufficient to isolate a unique profile within the database. As soon as the person is re-identified through their administrative and medical history, their entire genetic footprint is exposed.
In 2025, the British data protection authority (ICO) reminded (as others had before it) that if one can find anidentity by cross-referencing information, these files are not anonymous and must be protected in a very strict manner.
The abuses of purpose diversion
This model of circulation of these data opens the door to many misuses. Information initially collected for public health is diverted towards commercial, police or ideological objectives. Several risks are already materializing:
- During the CPRD affair in 2020 in the United Kingdom, the British Ministry of Health banked 10 million pounds sterling by selling access licenses to the medical records of millions of NHS patients to laboratories based in the United States (Merck, Bristol-Myers Squibb, Eli Lilly). The government claimed that these data were anonymous, but their level of detail allowed the identity of patients to be found. The same year, Amazon signed a partnership agreement with the NHS to exploit these health data to train and improve the algorithm of its voice assistant Alexa.
- In the United States, life insurance companies use health data or genetic risk scores to adjust their rates or refuse contracts to people predisposed to certain diseases. Similarly, recruitment companies have used medical information to screen out candidates deemed "at risk" or less productive.
- During the American ABCD study (Adolescent Brain Cognitive Development) on the brain development of 20,000 children, extremist researchers recovered medical data to attempt to produce pseudo-scientific research with a racist aim, seeking to link genetics and intelligence according to ethnicity. This phenomenon extended to the UK Biobank: the Human Diversity Foundation group would have accessed it to conduct controversial work on race and intelligence, while the start-up Heliospect Genomics would have used it to design embryo selection tools according to IQ. The Biobank claims that no evidence of abusive use has been established, but several geneticists consider its reaction too hasty and denounce a lack of control over the actual use of the extracted files.
- American law firms have managed to use access to hospital medical record sharing networks to do client prospecting. By targeting patients with specific diagnoses or victims of medical errors, they can thus approach them to encourage them to sue healthcare facilities or join class actions.
Marie Zins, Commissioner at the CNIL and former director of the Inserm Service Unit "Population Epidemiological Cohorts"
"The UK Biobank, by virtue of its size and the ease of access to its data, has been a reference within the scientific community and has inspired many other projects. All public health researchers know this database. Its broad policy of openness for access to the data has allowed a wide dissemination and a very large number of reuses. The incident reported here questions the relevance of this model.
As researchers, we have a moral responsibility towards the people who accept to trust us by sharing their data for research. At Inserm, I worked for many years on the Constances (220,000 participants) and Gazel (20,000 volunteers) cohorts, for which I was responsible. I was able to observe the evolutions of research practices and data sharing. At the beginning, the data were shared directly with researchers who needed them for their research projects. A significant part of our work consisted in following up the projects and in particular ensuring that the data were properly destroyed after the end of the research work. But when the data circulate and can be recopied, it is very difficult to ensure that each copy has been properly destroyed.
Over time, we moved from direct sharing of the data to making the data available on a secure platform that we controlled. On these infrastructures, data extractions are not allowed. We asked that each export be manually checked to ensure that it does not contain personal data. The risk of incidents such as the one of the UK Biobank is greatly reduced. In addition, the system records all the analyses made by the users, which allows checks in case of doubts about the proper use of the data.
It must be understood that the management of a secure data access infrastructure is a profession in its own right. It requires resources and specialized knowledge. This is why it is often more virtuous to pool these projects on a shared platform, rather than each one trying to secure their own data, without having the critical size to maintain their system at the state of the art. In the same way, it is necessary to challenge the idea that these secure access platforms are not suited to research because they would not offer all the analysis tools necessary for researchers, in particular for research wishing to use artificial intelligence tools. This does not seem correct to me: it is entirely possible to create spaces in which these tools are imported – after a prior check to ensure that they do not represent a risk to security – with infrastructures that quickly adapt to the needs expressed by researchers. To speak of my experience, we worked with the Secure Data Access Center (CASD), which covers all these needs while providing excellent guarantees on data protection. The upcoming arrival of the European Health Data Space raises the question of the data access model that we want, and I think that we must continue to go in this direction."
Marie Zins
Marie Zins holds a doctorate in medicine and epidemiology, and is qualified to supervise doctoral research. She was director of the Inserm Service Unit 'Population Epidemiological Cohorts' and head of two cohorts linked to the National Health Data System (SNDS) and the pension insurance databases: the National Constances Infrastructure, which with 220,000 participants represents the largest epidemiology and public health research project in France, and the Gazel cohort (20,000 volunteers followed for more than 35 years). She has been a member of the CNIL since February 2024.
And in France?
Access to health data for research is organized, by design, in centralized systems allowing the exploitation of data without exporting them. The national SNDS database respects a security reference that extends to all its child systems, including the Health Data Hub; hospital data warehouses have been regulated by the CNIL on a requirement of access to data in secure and supervised spaces, which also applies to any partners exceptionally receiving a copy of the data; data exports by researchers are limited to results whose anonymization is controlled beforehand; research projects are subject to the approval of a governance committee and/or an ethics committee.
Even if this may seem restrictive for researchers, this level of requirement responds to the finding that health data, even pseudonymized, are so rich and linked to the individual course of a patient that they inherently present a high risk of re-identification and exploitation for malicious purposes. Controlling their circulation and actively monitoring their use is therefore essential to protect the rights, and maintain the trust, of citizens and participants in research projects.
At a time when the new regulation for the European Health Data Space proposes to define the conditions of circulation and access to the data of European citizens for care and research, in a context of massive health data breaches, it appears more than necessary to rely on these proven principles of data protection by design.